
Cloudflare Squeezes 100TB from DNS Cache

Alps Wang
Sep 24, 2026 · 1 views
Memory Optimization at Scale
Cloudflare's recent optimization of its 1.1.1.1 DNS cache, detailed in the InfoQ article, represents a remarkable feat of engineering, demonstrating how deep dives into data structures and memory management can yield substantial gains even in mature systems. The reduction of 100 TB of working-set memory across their fleet is not merely an incremental improvement; it's a testament to the power of granular optimization. The shift from Vec and String to Box<[T]> and Box<str> for fixed data, along with clever techniques like packing booleans into bitflags and omitting owner names by reconstructing them from the cache key, highlights a meticulous approach to reducing per-entry overhead. This is particularly relevant for AI and database professionals who constantly grapple with memory efficiency, especially when dealing with massive datasets or high-throughput systems. The improved cache insertion throughput and reduced lookup latency further underscore the practical benefits of this architectural refinement.
The innovation lies not just in the magnitude of memory saved, but in the systematic, iterative process of redesigning the in-memory representation. Cloudflare's willingness to tackle Rust enum overhead by moving to a contiguous byte buffer using DNS wire format, directly addressing memory locality and allocation overhead, is a sophisticated solution. This approach contrasts with other resolvers that might focus on larger-scale cache partitioning. The article also wisely includes a Reddit commenter's perspective, acknowledging that such micro-optimizations are most impactful at Cloudflare's scale, serving as a crucial reminder for developers at smaller organizations about the trade-offs between complexity and benefit. Nevertheless, the principles of efficient data representation and allocation management are universally applicable and can inspire similar optimizations in other high-performance systems, including those powering AI model inference or large-scale database operations.
While the benefits are clear for Cloudflare and its users, the primary limitation for external adoption is the sheer scale of operations required to amortize the development effort and see the same level of impact. The article doesn't delve into the specific tooling or profiling methods used, which could be a valuable addition for those looking to replicate such efforts. Furthermore, the long-term maintenance and potential for future regressions in such a finely tuned system are considerations. However, for organizations managing vast amounts of data or serving millions of requests, the lessons learned from Cloudflare's Big Pineapple project offer invaluable insights into pushing the boundaries of memory efficiency and performance.
Key Points
- Cloudflare significantly reduced its 1.1.1.1 DNS cache memory footprint by 100 TB.
- This was achieved through a redesign of the in-memory representation, reducing per-entry footprint by 56% (from 953 to 420 bytes).
- Key technical changes include replacing
Vec/StringwithBox<[T]>/Box<str>, packing booleans into bitflags, and storing record data in a contiguous byte buffer using DNS wire format. - The optimization also increased cache insertion throughput by 43% and reduced lookup latency by 19%.
- The changes were rolled out across production between May and July 2026, leading to a substantial decrease in resident memory per instance.
- The freed memory will be used to increase cache capacity without increasing overall memory consumption.
- The effectiveness of these micro-optimizations is scale-dependent, with significant benefits realized at Cloudflare's request volume.
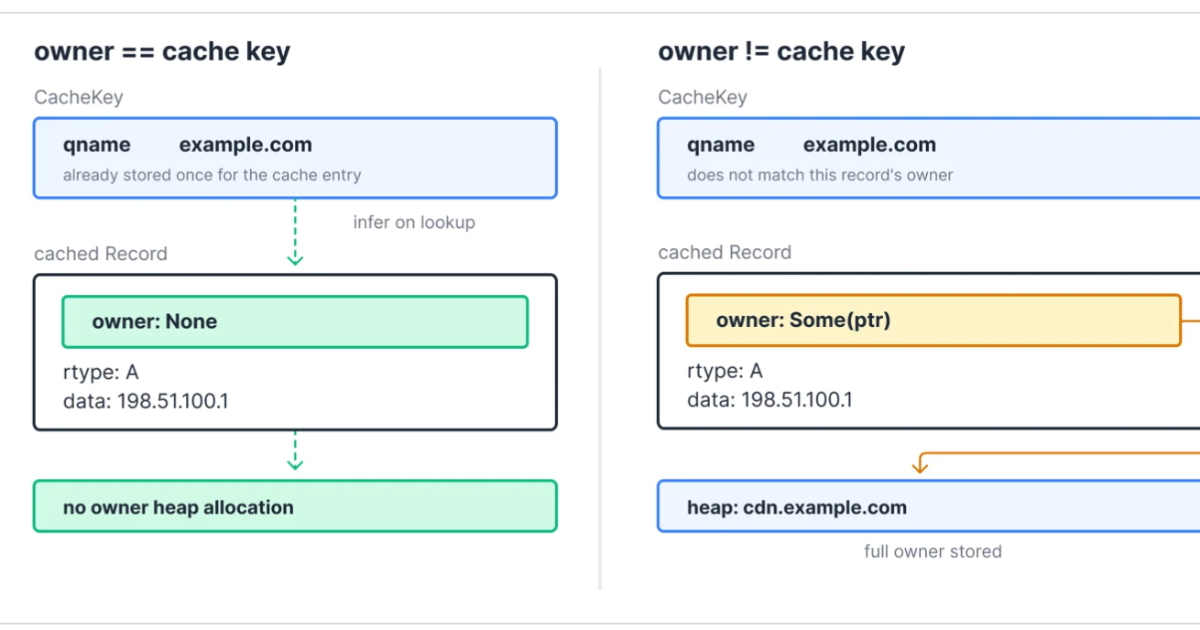
📖 Source: Cloudflare Cuts 100 TB of Memory from 1.1.1.1 DNS Cache
Related Articles
Comments (0)
No comments yet. Be the first to comment!